The short version
- Word error rate compares machine output to a human reference transcript and counts substitutions, deletions, and insertions.
- The same system will get a different score if you change the normalization rules, the spelling conventions, or the test audio.
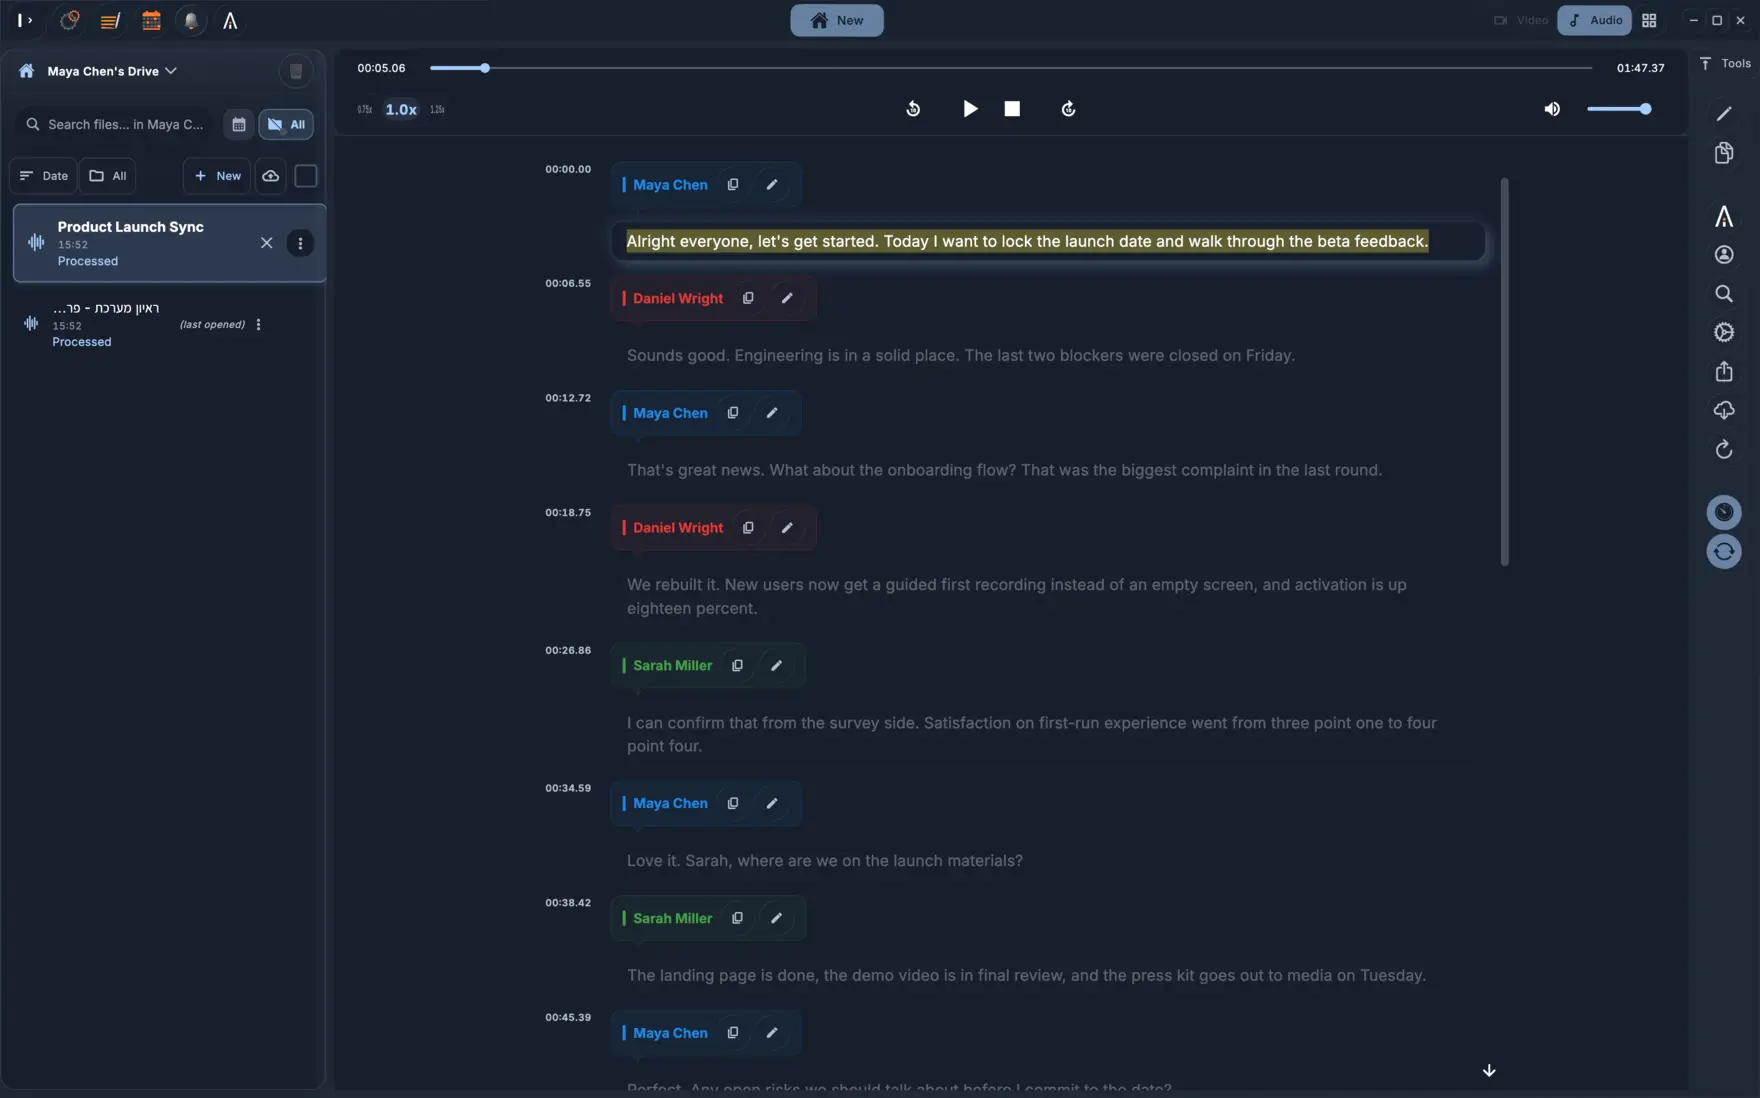
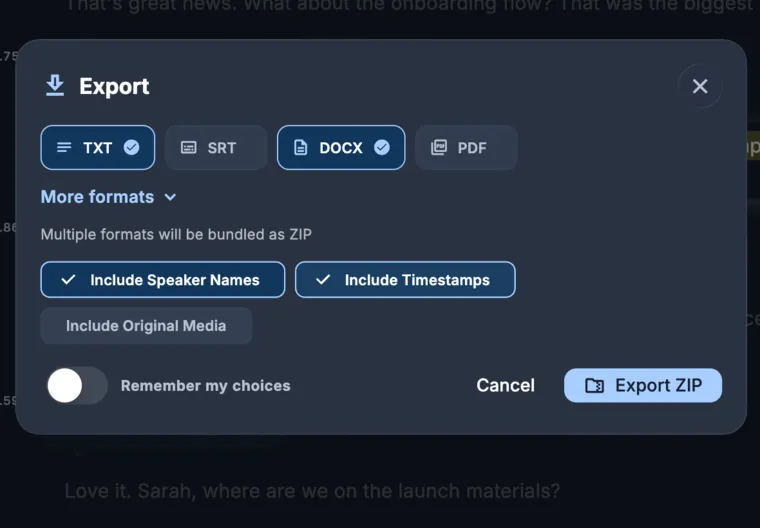
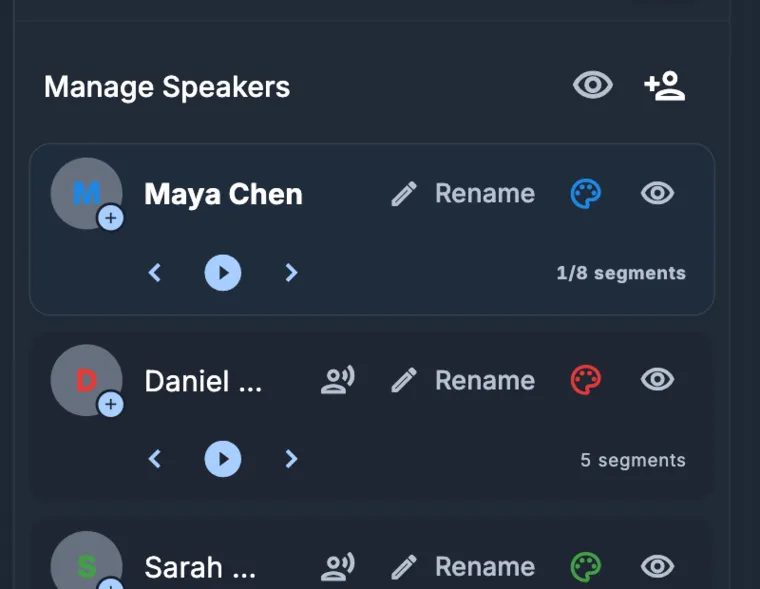
- You have to check speaker labels, timestamps, dropped passages, proper names, and export formatting separately.
- The most useful benchmark is a fixed set of your own recordings, scored under the exact same rules every time.
- We do not publish a single accuracy percentage for KolWrite because no single number holds up across different people's audio.
1. How word error rate is calculated
Word error rate, usually shortened to WER, compares a machine output to a reference written by a person. It counts three types of mistakes: wrong words, missing words, and added words. That total gets divided by the word count of the human reference. Because even a simple metric like this depends on how the two texts are prepared and matched up, NIST evaluation programs include standardized scoring tools with their plans.1
This metric works well in a controlled test where both sides use the same audio, the same reference text, and the same rules. It loses its meaning when one system removes filler words while another keeps them, or when one reference leaves a borrowed name in Latin letters and the other transliterates it. The number itself isn't wrong, it just answers a different question.
2. Why the test audio matters more than the model
Someone reading aloud into a good microphone cannot stand in for a support call, a lecture hall, or four people gathered around a laptop. In 2022, work on weakly supervised training reported its results broken down by dataset and by language, rather than giving a single headline figure. That is the honest way to report.2
Careless comparisons break down even faster in Hebrew and Arabic. For one thing, spelling conventions decide what counts as a single word. How hard a file is also depends on the dialect, how much speakers switch between languages, and how much of the speech is spontaneous. A 2024 Hebrew dataset was created partly to add more unscripted speech to a small existing pool, while Arabic research treats dialectal, mixed-language speech as a distinct problem.345
3. What a single score misses
A WER score won't tell you if the words were assigned to the wrong speaker. It doesn't catch timestamps that drift off track, a whole minute of audio lost when a retry fails, or subtitle lines that are too long to read before they disappear. It also penalizes a missing "the" and a wrong medication dosage equally.
Instead of relying on one score, we track six separate things: missing audio, word accuracy, speaker attribution, names and numbers, timing, and how many minutes a person spends cleaning up the text. If the final output is a formatted document or a subtitle file, we check export fidelity too. That gives you a practical checklist anyone can run again later.
4. How a small team can run a fair benchmark
Put together a fixed batch of recordings that match your actual day-to-day work. Include clean and noisy audio, short clips and long ones, solo speakers and groups of five, and the specific mix of languages your team uses. Save the original audio files, the human reference transcripts, the exact settings, and the date of each test. If you quietly swap out hard files for easier ones over time, your benchmark stops being useful.
When possible, don't tell the person reviewing the text which tool produced it. Count the errors before anyone edits the transcript, and log the automated score right next to the minutes spent fixing it by hand. Re-run the test whenever a model or pipeline changes, and leave the toughest recordings in the folder even if the scores look bad.
5. What a real accuracy claim looks like
A useful accuracy claim tells you the language, the subject matter, the dataset, the recording conditions, the metric used, the text normalization rules, the number of files tested, the product version, and the date. It also states what was left out of the test. Without those details, a percentage is just marketing.
We have not published an accuracy number for KolWrite, and we are not going to make one up for a page like this. Instead, we suggest a duller, more useful comparison. Run the same difficult recordings through each tool, check the names and speakers against the audio, finish the export you would actually send out, and count how much work is left over.
Common questions
What does 99% accurate mean?
By itself, almost nothing. It may just mean the tool made one mistake per hundred reference words under a specific set of normalization rules, using audio files the vendor picked. Always ask which recordings were used, along with the metric, the scoring rules, and the date of the test. If you don't get those details, treat the number as an ad.
Can two tools score differently on the same audio?
Yes, very easily. The score will shift depending on which human reference transcript you use and how you handle punctuation, numbers, filler words, and spelling variations. To get a fair comparison, you have to lock down all of those rules before you score anything.
What should we measure besides word error rate?
Look at dropped audio passages, speaker labels, names and numbers, word or segment timing, caption formatting, export quality, how often jobs fail outright, and how long it takes a person to edit the file into a finished state.
Is a public benchmark enough to choose a tool?
It is only a starting point. Public datasets rarely match your room acoustics, your speakers' accents, or your industry terms. Scoring ten of your own recordings the same way across tools will tell you much more than a public leaderboard built on someone else's audio.
Sources and further reading
- 1NIST, Open Speech Analytic Technologies Pilot Evaluation Plan
- 2Radford et al., Robust Speech Recognition via Large-Scale Weak Supervision
- 3Turetzky et al., HebDB: a Weakly Supervised Dataset for Hebrew Speech Processing
- 4Hamed et al., Dialectal Arabic-English Code-Switching Speech Recognition
- 5Chi & Bell, Improving Code-switched ASR with Linguistic Information